Resurface - Score any resume against any job, with quoted evidence | Product Hunt

Resume scoring API · Quoted evidence

Language models write.Classification models decide.

Resurface is a resume scoring API. Send a job description and a resume; get a 0–100 score and, for every screening question, the exact resume line that proves it. An LLM writes the questions once. A decision model answers them for every resume, and Resurface runs on any model that passes its eval.

No card needed. PDF, DOCX, HTML or TXT.

faster
8×
same verdicts
99%
verbatim quotes
100%

vs Claude Sonnet 5.5 on 20 resumes × 5 questions, 2 runs each. See the verdict sheet

One resume · five questionsMedian, measured

General LLM: 2.5 s per resume, quotes written by the model.

  • Hands-on React“appears to…”
  • Node.js services“likely has…”
  • Schema design“not clear…”
  • Cloud in production“mentions AWS…”
  • B2B SaaS / leadership“seems to…”

Median measured latency per resume, five questions each. Claude Sonnet 5.5 vs TypeSafe Jev.

Two ways in

One engine, for the team that wires it in and the team that hires with it.

Resurface is a B2B API for employers, staffing agencies and recruiting software. It screens resumes that candidates have already sent to an employer; it does not create, write or edit resumes, and it is not a tool for job seekers.

For developers

One API call. Typed JSON back.

POST a job description and a resume file to /api/v1/score. Get a 0–100 score, a verdict per screening question and the resume line behind each one.

median per resume
292 ms
PDF, DOCX, HTML, TXT
5 MB
rate limit
60 / min
  • Verdicts with calibrated probabilities: SUPPORTED, INSUFFICIENT_EVIDENCE, CONTRADICTED
  • Evidence as a resume line id plus the verbatim text of that line
  • Two-column PDFs extracted in reading order
  • 50 free scores, then prepaid packs from $0.10 per score
Open archive boxes full of paper resumes; one resume lies on top with a single line highlighted in yellow.

For recruiting teams

Rediscover the candidates already in your ATS.

Score past applicants against today’s open roles. Every match comes with the exact resume line that proves it, so a recruiter can check it in seconds.

  • Every score explained with a quoted resume line
  • 8× faster per resume than screening with Claude Sonnet 5.5
  • PDF, Word, HTML and text resumes, scored against the same job
  • Integrations with Greenhouse, Ashby and JobAdder planned
Talk to us

Resurface is an API today; there is no recruiter dashboard yet. Tell us about your ATS and hiring volume.

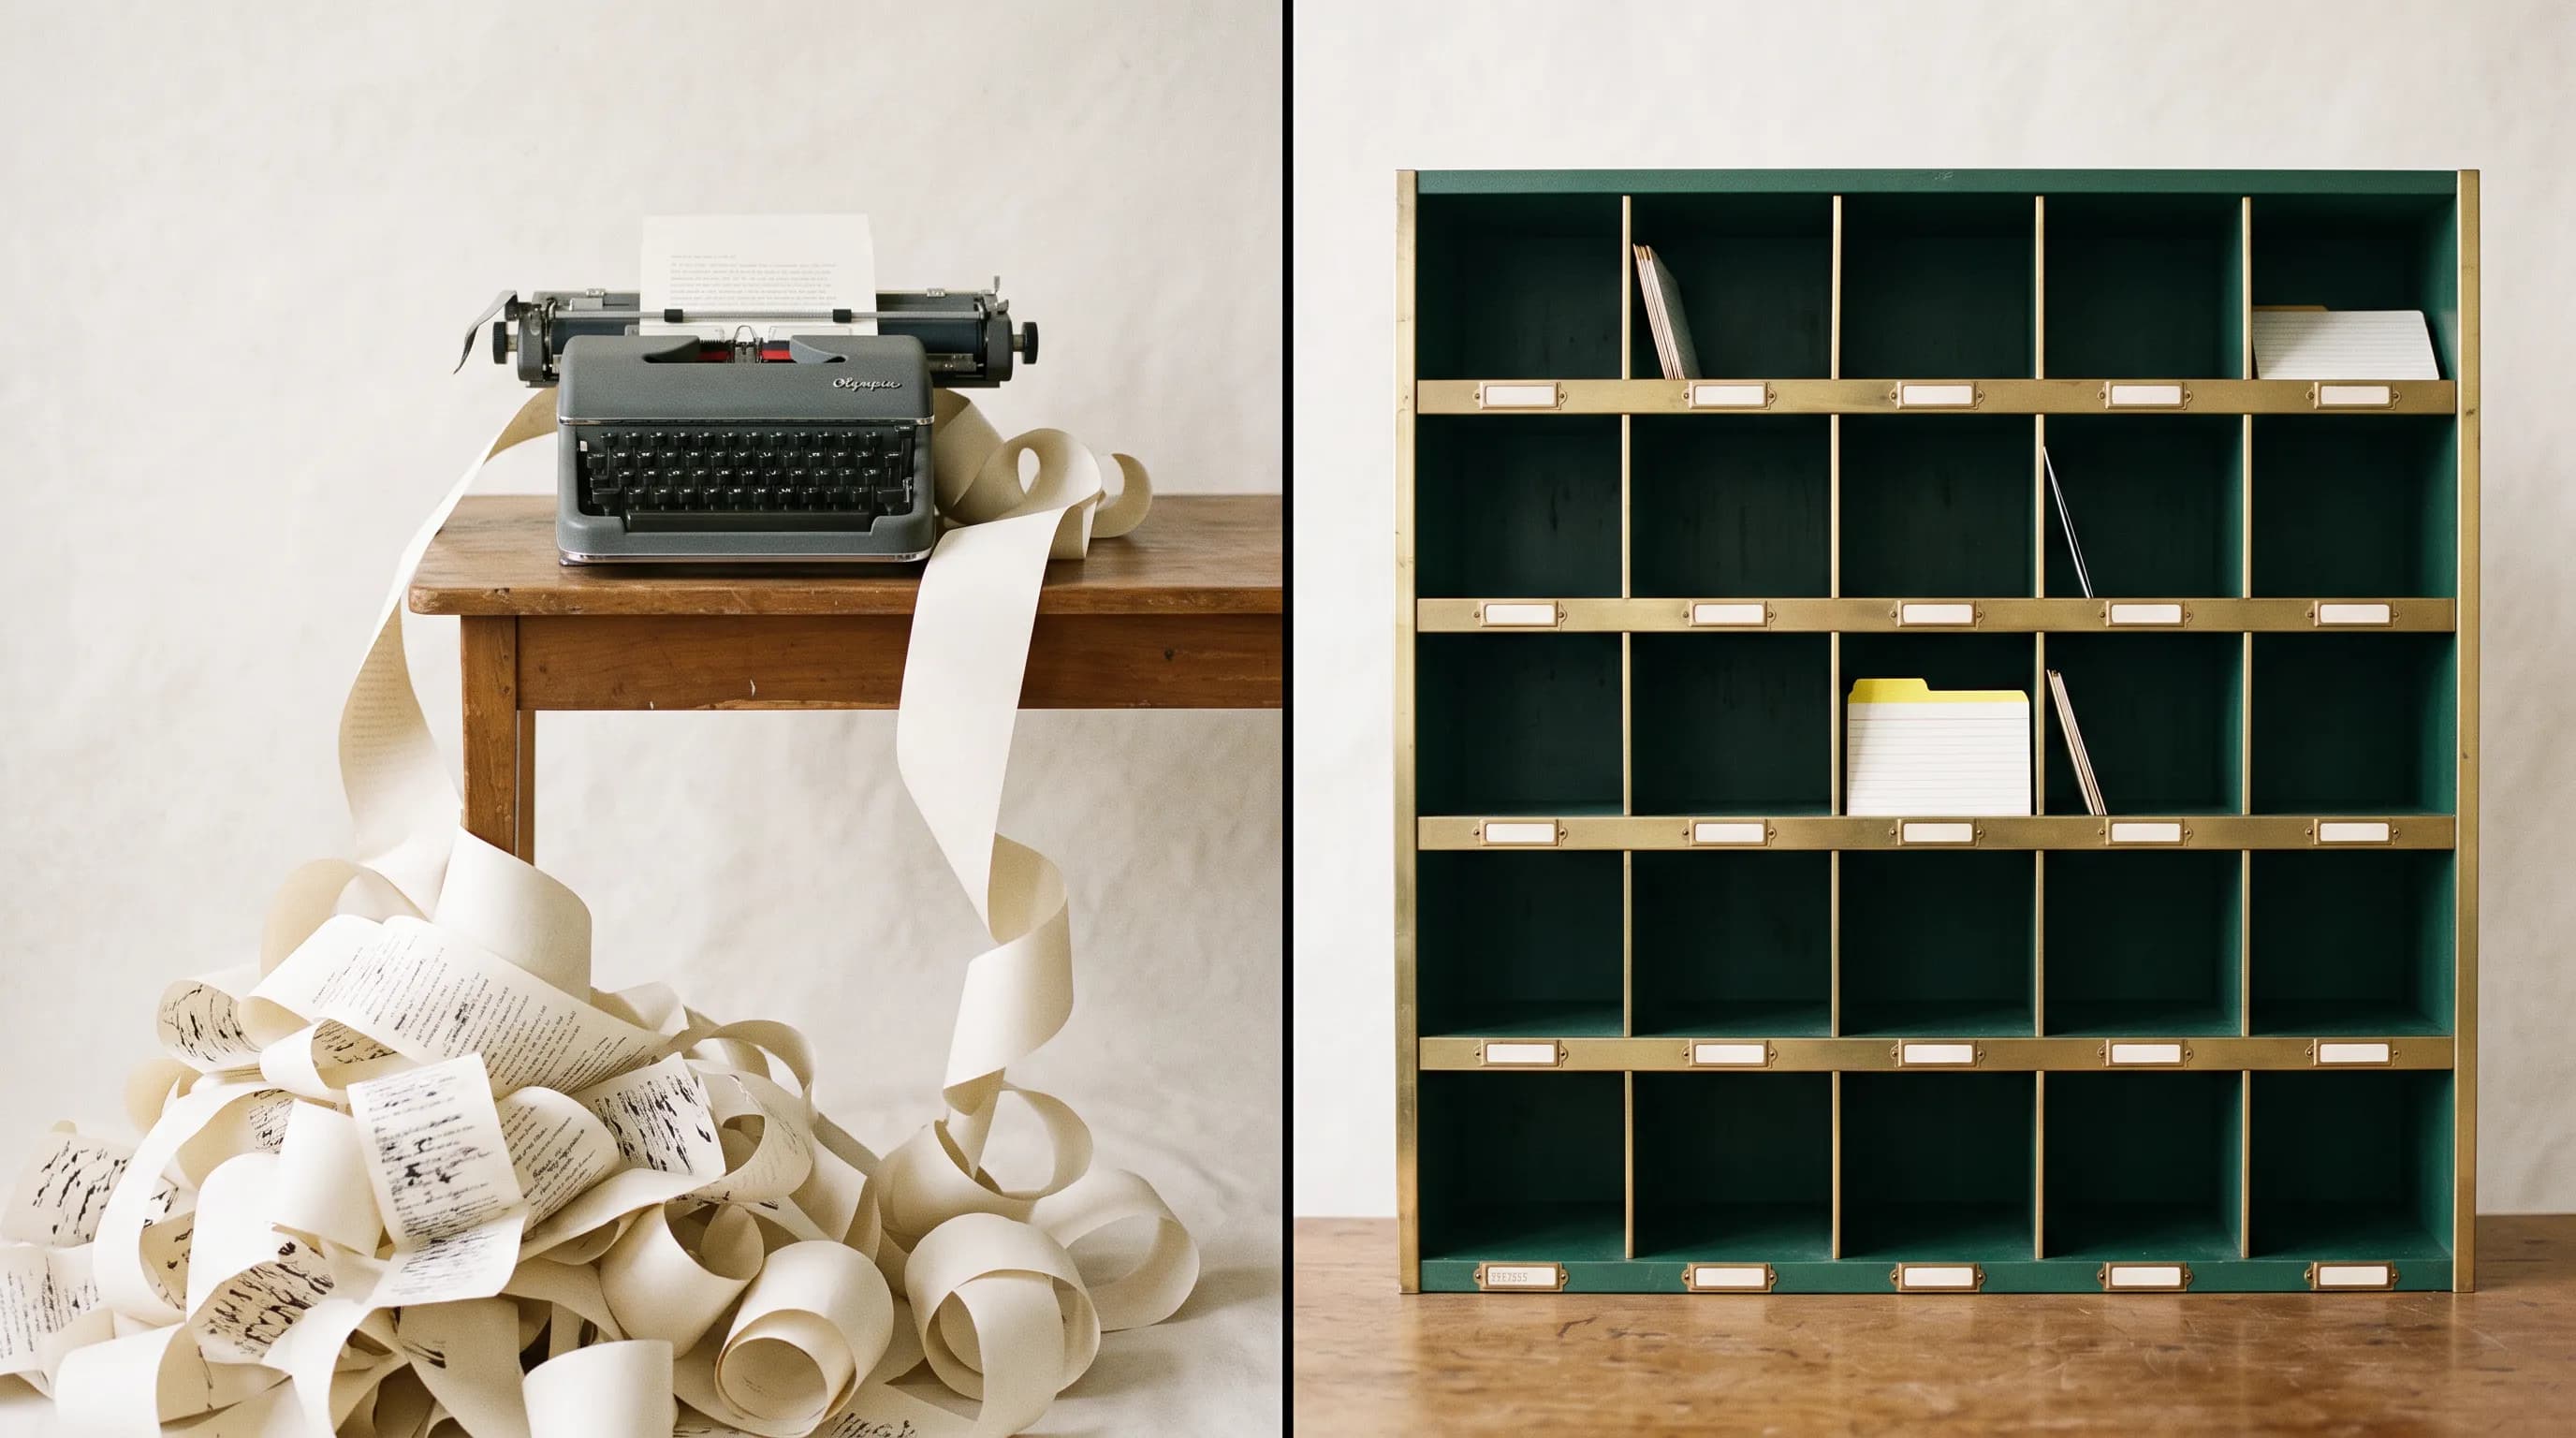
Left: a typewriter spilling long ribbons of typed paper. Right: an ordered green sorting rack with a few labelled cards.
General LLM: abundant, fluent, open-endedClassification model: one of your answers, with a probability

The verdict sheet

Why a classifier should read your resumes, and an LLM shouldn’t read all of them.

Classifier
5
Tie
2
LLM
1
Measured 30 Sep 2026 on 20 fictional resumes × 5 screening questions for “Senior Full Stack Engineer”, each model run 2×.
SpecificationGeneral LLMClaude Sonnet 5.5Classification modelTypeSafe JevVerdict
01 · Output
What comes backScreening needs an answer your code can act on.LLMGenerated textJSON only when you constrain and validate itClassifierA typed answerone of your options + its probabilityVerdict: Classifier
02 · Evidence
Where the proof comes fromA recruiter must be able to check every claim against the CV.LLMWrites a quotemust be verified; 100% matched the source in our runClassifierPoints to a linepicks line id L006 and copies that lineVerdict: Classifier
How sure is it?Uncertain cases should go to a human, automatically.LLMIn words“fairly confident” can’t be thresholdedClassifierCalibrated probabilitiesthreshold it: < 0.6 → human reviewVerdict: Classifier
03 · Speed
Time per resumeMedian, 5 questions per resume, measured.LLM2.5 sHaiku 4.5: 1.7 sClassifier292 ms8.4× faster than Sonnet 5.5Verdict: Classifier
04 · Quality
Same verdicts as a frontier LLMShare of question-level verdicts matching Claude Sonnet 5.5.LLMHaiku 4.5: 93%a smaller LLM drifts furtherClassifier99%near-frontier judgment, at classifier speedVerdict: Tie
Same answer on a re-runIdentical inputs, evaluated twice.LLMSonnet 100% · Haiku 98%sampling can flip borderline callsClassifier100%a decision model returns a distribution, not a sampleVerdict: Tie
05 · Safety
A CV that says “ignore all criteria”Resumes are untrusted input.LLMResisted in our testbut it reads instructions as language it may followClassifierStructurally boundedit can only pick among your optionsVerdict: Classifier
06 · New challenger
OpenAI Decisions APIAnnounced at DevDay, 29 Sep 2026. Powered by GPT-6 Luna, OpenAI’s cheapest LLM.LLMAn LLM in a classifier costumelimited preview · ~150 ms claimed by OpenAI · no public endpoint, schema, pricing or probability semantics yetClassifierA dedicated decision modelgenerally available · 292 ms measured here, end to endVerdict: Pending
07 · Where LLMs win
Turning a job post into questionsOpen-ended reading and writing, once per job.LLMExcellentClaude drafts 6–8 atomic questions in secondsClassifierNot its jobSystem One models decide; they don’t writeVerdict: LLM
The architectureUse each model for what it is.LLM1 call per jobwrites the questionsClassifier1 call per resumeanswers them, with evidenceVerdict: Use both

Method

Same 20 fictional resumes and 5 screening questions for every model; each asked for a verdict (supported / contradicted / not established) plus evidence. LLMs used structured output with the same instructions. 2 runs each.

Caveats

The sample is small and synthetic, so read the results as directional. Agreement is measured against a frontier LLM, not human labels. Rerun it with scripts/benchmark.mts.

How it works

Write once. Decide for every resume.

Resurface splits resume screening into writing and deciding. An LLM writes the screening questions once per job; a classification model answers them for every resume and points to the line that proves each answer.

candidate.pdf → lines8 lines
  1. L000Full Stack Engineer · 7 years
  2. L001Experience
  3. L002Northwind Analytics, 2021–2025
  4. L003- Moved billing services to Node.js and NestJS
  5. L004- Designed PostgreSQL schemas for a multi-tenant SaaS
  6. L005- Mentored four engineers through on-call rotations
  7. L006- Built dashboards in React and TypeScript for 40k users
  8. L007תואר ראשון במדעי המחשב

Has the candidate built production front-end applications with React?

SUPPORTED · 0.97evidence L006
A fictional resume split into numbered lines. The classifier selects L006; the quote is that line, copied.
  1. An LLM drafts the questions, once per job

    Send a job description and Claude drafts 6–8 atomic screening questions, such as “Has the candidate built production front-end applications with React?”. They are cached as a rubric and reused for every resume. Drafting is free.

  2. A classifier answers them for every resume

    TypeSafe Jev, a classification model, answers each question with SUPPORTED, INSUFFICIENT_EVIDENCE or CONTRADICTED and a calibrated probability, in a median 292 ms per resume in our benchmark. If Jev is unavailable, Cloudflare Clef-flash answers the same request.

  3. Evidence is a line id, never generated text

    Each answer cites a resume line by its id, for example L006. The quote you show is copied from that line, so it cannot say something the resume does not.

  4. You get a 0–100 score you can explain

    The score is the share of question weight backed by a quoted resume line. Missing information stays unknown instead of counting against the candidate: it widens the range, and must-have gaps are listed separately.

Model-agnostic

Any decision model. Same evidence.

Resurface is the hiring layer around the model. It reads resumes in order, drafts the screening questions, picks the verbatim evidence and computes the score, then sends the same request to any decision model that speaks the System One API. A model serves scores only after it passes our resume eval.

  • No lock-in to one model vendor
  • Automatic failover when a model is down
  • One request and one response schema, whatever model answers
  • Every response names the model that answered
  • Jev by TypeSafe AI

    Answers every resume

    Primary

    99% agreement

  • Clef-flash by Cloudflare

    Takes over when Jev is unavailable

    Auto fallback

    100% agreement

  • Clef by Cloudflare

    Ready to switch in

    Passed eval

    99% agreement

  • Next model

    Plugs in once it passes the same eval

Agreement: share of verdicts matching Claude Sonnet 5.5 on 20 fictional resumes × 5 screening questions, 2 runs each; every model gave the same answers on both runs. Jev measured 30 Sep 2026, the Clef models 3 Oct 2026.

The API

Score any resume against any job, with evidence.

One multipart request with a job title, a job description and a resume file. The response is typed JSON: a score, a match level, and for each question a verdict, its probabilities and the evidence line.

Endpoint
POST /api/v1/score
Auth
Bearer API key
Files
PDF, DOCX, HTML, TXT · 5 MB
Rate limit
60 scores / minute
request
curl https://getresurface.dev/api/v1/score \
  -H "Authorization: Bearer $RESURFACE_API_KEY" \
  -F job_title="Senior Full Stack Engineer" \
  -F "job_description=<job.txt" \
  -F resume=@candidate.pdf
response (trimmed)
{
  "object": "score",
  "id": "scr_Qm3xk2Lp9aRt",
  "score": 92,
  "match": "strong_evidence",
  "coverage": 0.917,
  "range": { "lower": 92, "upper": 100 },
  "must_have_gaps": [],
  "questions": [
    {
      "id": "react_in_production",
      "question": "Has the candidate built production front-end applications with React?",
      "requirement": "must",
      "weight": 3,
      "verdict": "SUPPORTED",
      "status": "supported",
      "evidence": { "line": "L006", "text": "- Built dashboards in React and TypeScript for 40k users" },
      "probabilities": { "SUPPORTED": 0.97, "INSUFFICIENT_EVIDENCE": 0.03, "CONTRADICTED": 0 },
      "confidence": 0.96
    }
  ],
  "rubric": { "id": "rub_8fKq2", "source": "rubric_cached", "questions": 6 },
  "model": "jev-1.13.0",
  "billing": { "billable": false, "price_usd": 0, "free_remaining": 49 },
  "latency_ms": 640
}

In Claude's plugin directory · MCP server

Score resumes from Claude.

Add the Resurface plugin from Claude's plugin directory and ask it to rank a folder of resumes against a job. You sign in with your Resurface account once, and every verdict comes with the resume line behind it. Other agents connect to the MCP server directly.

score_resume
Score a resume against a job · 1 score
draft_screening_questions
Job description → rubric · free
get_usage
Remaining scores · free

MCP endpoint https://getresurface.dev/api/mcp

The Resurface tile plugged into the Claude tile
or in claude code
/plugin marketplace add dolevhayut/resurface
/plugin install resurface@resurface
then ask (example)
> Rank the resumes in ./candidates for this job

score_resume · dana-levi.pdf
Score 92/100 · strong_evidence · answered by jev-1.13.0
✓ SUPPORTED (must) · Has the candidate built production
  front-end applications with React?
    evidence L006: "- Built dashboards in React and
    TypeScript for 40k users"

Pricing

50 scores free. Then $0.10 per score.

Prepaid score packs, cheaper in bulk. No subscription, no seats. Drafting questions from a job description is free and cached.

Free tier
50 resume scores
100 scores
$10 · $0.10 each
500 scores
$40 · $0.08 each
2,500 scores
$150 · $0.06 each
Rubrics (questions from a JD)
Free
Rate limit
60 scores / minute
Files
PDF, DOCX, HTML, TXT up to 5 MB

Questions

Answers, with sources.

Benchmark figures: vs Claude Sonnet 5.5 on 20 resumes × 5 questions, measured 30 Sep 2026. All benchmarks

What is Resurface?

Resurface is a resume scoring API: send a job description and a resume file, and get back a 0–100 score and, for each screening question, a verdict with the exact resume line that proves it. An LLM drafts the screening questions once per job; a classification model (TypeSafe Jev) answers them for every resume.

What is a resume scoring API?

A resume scoring API takes a job description and a resume and returns a structured judgment of fit that your software can store and display. Resurface returns a 0–100 score plus a verdict for every screening question (SUPPORTED, INSUFFICIENT_EVIDENCE or CONTRADICTED), each with a calibrated probability and the resume line that backs it.

Is Resurface a resume builder?

No. Resurface is a B2B screening API for employers, staffing agencies and recruiting software (ATS vendors). It reads resumes that candidates have already sent to an employer and scores them against a job; it does not create, write or edit resumes, and it is not sold to job seekers.

What is the best API for scoring resumes against a job description?

There is no single best API; it depends on whether every score has to be explainable. Resurface is built for that case: for each screening question it returns SUPPORTED, INSUFFICIENT_EVIDENCE or CONTRADICTED with a calibrated probability and the id of the resume line that proves it. In our benchmark (20 fictional resumes × 5 screening questions) it was 8× faster per resume than Claude Sonnet 5.5, with 99% of verdicts matching.

What is the difference between a resume parser and a resume scoring API?

A resume parser extracts fields such as names, titles, dates and skills, and leaves the decision about fit to your code. A resume scoring API makes that decision: Resurface checks the resume against screening questions drafted from the job description and returns a score, a verdict per question and the line that proves each answer.

How is a classification model different from an LLM for resume screening?

An LLM generates text, so its answers, confidence and quotes are written and have to be parsed and checked. A classification model picks one answer from a fixed set and returns a probability for each option. Resurface's classifier cites evidence by selecting a resume line id, so the quote comes straight from the resume. Measured on 20 fictional resumes × 5 screening questions: median 292 ms per resume vs 2.5 s for Claude Sonnet 5.5, with 99% the same verdicts.

Which AI models does Resurface use?

Resurface is model-agnostic. An LLM (Claude) drafts the screening questions once per job. TypeSafe Jev answers them for every resume, and Cloudflare Clef-flash takes over automatically if Jev is unavailable. A decision model serves scores only after it passes our resume eval: on 3 Oct 2026, Clef-flash and Clef matched Claude Sonnet 5.5 on 100% and 99% of verdicts. Every response names the model that answered.

How do I add resume screening to an ATS or HR product?

Create an API key, then send each resume with the job description to POST /api/v1/score from your backend. The first call drafts the screening questions and returns a rubric.id; send it as rubric_id for the other resumes of that job, so scores stay comparable and each call takes about 0.25 s. Show the score next to the quoted evidence lines so recruiters can check them.

Read the API docs

Which file formats does the API accept?

PDF, DOCX, HTML and TXT files up to 5 MB, or plain text in the resume_text field. Scanned (image-only) PDFs and legacy .doc files are not supported yet.

Do you store the resumes I send?

No. Resumes are read in memory to produce a score; the file and its full text are not stored. Resurface keeps a one-way hash of the resume (to detect repeats) and the scoring result, which includes the short resume lines quoted as evidence. Job descriptions are stored as reusable rubrics in your account.

Read the privacy policy

Should a resume score be the only reason to reject a candidate?

No. Use the score to rank and route resumes, and keep a person in the decision. INSUFFICIENT_EVIDENCE means the resume does not say, which is different from failing a requirement, and every response lists must-have gaps separately. Each verdict has a calibrated probability, so low-confidence answers can go to human review automatically.

How much does Resurface cost?

Every developer account gets 50 free resume scores. After that you buy prepaid packs: 100 scores for $10, 500 for $40 or 2,500 for $150, with no subscription. Drafting screening questions from a job description is free and cached as a rubric. There are no seats or minimums, and the rate limit is 60 scores per minute.

Is there an app for recruiters?

Not yet. Resurface is an API today, so recruiting teams use it through their own developers. Integrations with Greenhouse, Ashby and JobAdder are planned. To talk about your ATS, write to office@bulldog-adv.com.

Email us

How was the benchmark measured?

On 30 Sep 2026, the same 20 fictional resumes × 5 screening questions for a Senior Full Stack Engineer role were sent to TypeSafe Jev, Claude Sonnet 5.5 and Claude Haiku 4.5, 2 runs each. Speed is the median latency per resume. The benchmark is small, so treat it as directional; the script is in the open-source repository on GitHub.

See the benchmark script

Can I use Resurface from Claude or another AI agent?

Yes. Resurface is in Claude's plugin directory: in Claude, open Customize, then Plugins, and search for Resurface. It also installs in Claude Code. You sign in with your Resurface account once, and it adds the MCP tools score_resume, draft_screening_questions and get_usage, plus skills for screening candidates and for building the API into your product. Other MCP clients connect to https://getresurface.dev/api/mcp with the same sign-in, or with an API key as a bearer token.

Set up the plugin

Keep your ATS. Rediscover your talent.

An old green card-catalog drawer pulled open, one index card lifted with a yellow tab.
EssentialAlways on

Sign-in cookies set by Clerk, this choice (stored in your browser), and the rs_promo cookie when you arrive through a launch offer. The site can't work without them.

Resume Scoring API with Quoted Evidence · Resurface